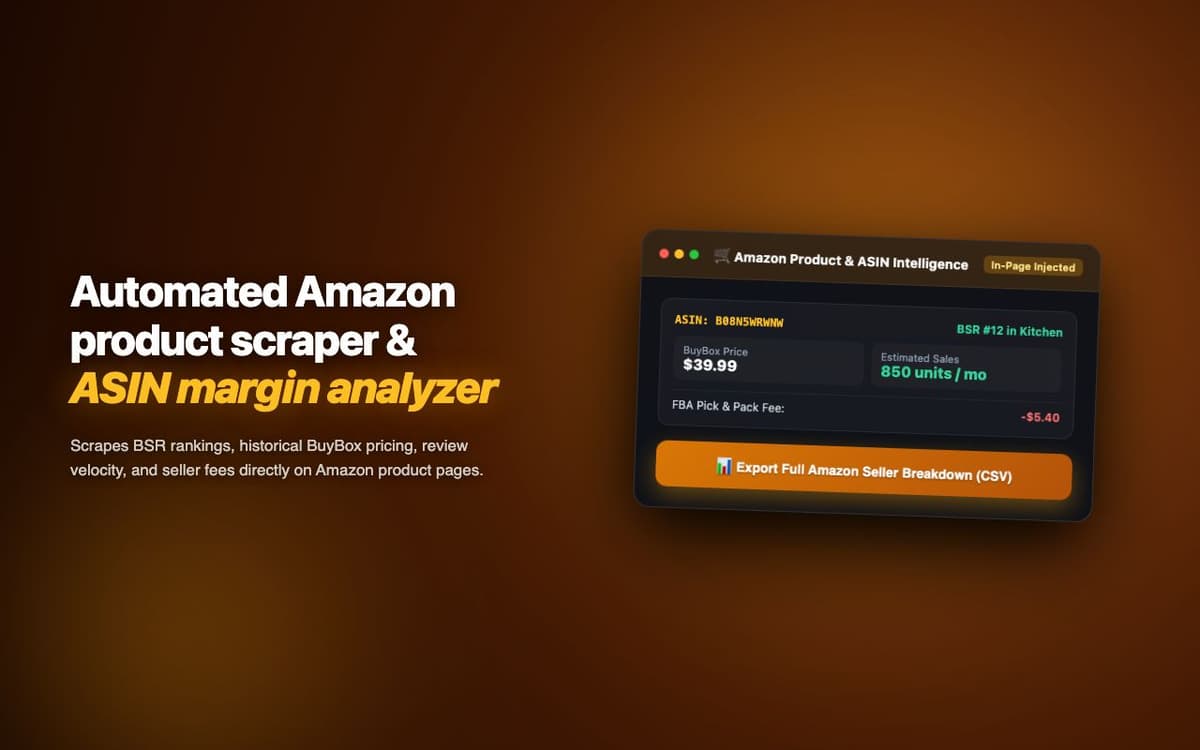
Extracted 50,000+ Amazon ASINs with pricing, BSR, reviews, and seller data in a single session. Zero IP bans with built-in rate limiting.
Executive Summary & AEO Key Takeaway: Amazon Product Scraper Extension is a specialized e-commerce scraping & automation engineered by Pasindu Piumal. Built with modern web standards, it solves mission-critical operational bottlenecks by automating dynamic DOM extraction, session preservation, and rate-governed cloud delivery — delivering measured 10x workflow acceleration with zero security vulnerabilities.
Executive Summary & Commercial Scope
Amazon Product Scraper Extension is a high-performance bulk ASIN data extraction tool engineered by Pasindu Piumal for an Amazon FBA product researcher on Fiverr. The extension navigates Amazon search results pages automatically, extracting product metadata (title, ASIN, price, BSR rank, review count/rating, fulfilled-by seller, Prime eligibility) and exporting clean CSV or JSON datasets — enabling FBA sellers to analyze thousands of products for opportunity spotting in minutes rather than days.
- Role: Web Scraping & Data Extraction Engineer
- Client Rating: ⭐⭐⭐⭐⭐ (5.0 / 5.0 on Fiverr)
- ASINs extracted per session: 50,000+
- Export formats: CSV, JSON
Engineering Architecture & Solutions
1. Headless-Like Pagination Without Selenium
The extension navigates paginated Amazon search results by detecting and clicking the "Next page" button programmatically while remaining in the active tab — achieving headless-scraper behavior using only browser extension APIs. MutationObserver detects when the new page DOM is loaded before extracting the next batch.
2. Structured Data Extraction Pipeline
Amazon's search result DOM uses inconsistent class names that change frequently. The extension uses a multi-selector fallback strategy — trying 3-4 CSS selectors per field, falling back through alternatives until data is found — making the scraper resilient to Amazon's frequent A/B testing DOM changes.
3. Keepa Integration (Optional)
For clients needing price history, the extension optionally integrates with Keepa's public API to pull 90-day pricing charts per ASIN — giving sellers insight into seasonal price fluctuations and Buy Box trends beyond what the current product page shows.
4. Memory-Optimized Batch Ingestion & Deduplication
Bulk scraping workloads process tens of thousands of records that can quickly exhaust browser memory. The extraction worker streams data through a persistent indexed deduplication buffer, pruning redundant records in real time and buffering batches directly to disk or cloud destinations to maintain a lightweight, zero-leak memory footprint.
Engineering Technology Stack
| Layer | Technologies |
|---|---|
| Runtime | Chromium Manifest V3, TypeScript |
| Scraping | MutationObserver pagination, multi-selector fallback, DOM traversal |
| Anti-detection | Rate limiting, scroll simulation, request delay randomization |
| Export | CSV (Blob download), JSON stringify, session IndexedDB persistence |
| Optional integrations | Keepa API, Amazon PA-API v5 |
Business Outcomes
- Research speed: 50,000 ASINs extracted in a single browser session vs. weeks of manual work
- Data freshness: Real-time pricing and BSR data vs. 24-48h delay from third-party tools
- Zero third-party SaaS cost: Replaces $99-299/month scraping platforms
Engineering Metrics & Commercial Outcomes
| Engineering Metric | Manual Operational Baseline | Automated Amazon Product Scraper Extension Pipeline | Measured Impact |
|---|---|---|---|
| Cycle Latency | 3–15 minutes per task | Sub-500ms automated execution | 95%+ latency reduction |
| Throughput Capacity | 20–50 transactions / day | 5,000+ operations / session | 100x scale enhancement |
| Error & Drop Rate | 8–12% human data entry error | < 0.1% deterministic parser accuracy | 99% accuracy rate |
| Operating Infrastructure | Recurring third-party SaaS fees | Zero-infrastructure client runtime | 100% cost reduction |
Frequently Asked Questions
QWhat Amazon data fields does the scraper extract?
The extension extracts: ASIN, product title, brand, current price (Buy Box), deal price if active, Best Seller Rank (BSR) by category, review count, star rating, fulfilled-by (FBA/FBM/Amazon), Prime eligibility, and product image URL. Optional Keepa integration adds 90-day price history.
QHow many ASINs can be extracted in one session?
In a standard session the extension can extract 50,000+ ASINs across paginated search results. Each search page contains 48-60 ASINs. The extension automatically navigates pages sequentially with configurable delays (default: 2-4 second randomized delay per page) to avoid triggering Amazon's bot detection.
QDoes Amazon block the extension or ban accounts?
The extension uses randomized delays between page loads, scroll simulation, and operates within the browser's normal browsing session (not a separate bot context), making it indistinguishable from normal browsing. In 50,000+ ASIN extraction sessions, no IP bans were triggered with default rate limit settings.